

Artificial Intelligence (AI) is transforming industries, and Large Language Models (LLMs) are at the center of this revolution. From AI-powered chatbots and virtual assistants to content generation, coding assistants, and enterprise automation, LLMs are enabling businesses to build intelligent applications that improve productivity and customer experiences.
However, building an LLM is only one part of the process. The real challenge begins when you need to make it available for real-world use. Understanding how to deploy Large Language Model solutions efficiently is essential for delivering fast, secure, and scalable AI applications. A poorly deployed model can lead to slow response times, high infrastructure costs, security risks, and poor user experiences.
This comprehensive guide explains how to deploy Large Language Model applications step by step. You’ll learn about deployment architectures, infrastructure requirements, optimization techniques, common challenges, deployment strategies, and best practices for running LLMs in production. Whether you’re a developer, data scientist, AI engineer, or business leader, this guide will help you build reliable, production-ready AI systems.
What Is a Large Language Model (LLM)?
A Large Language Model (LLM) is an advanced artificial intelligence model trained on massive datasets, including books, websites, research papers, code repositories, and other textual content. Using deep learning and transformer-based architectures, LLMs can understand context, generate human-like responses, summarize text, translate languages, answer questions, write code, and perform many other natural language processing (NLP) tasks.
Before learning how to deploy Large Language Model applications, it is important to understand how LLMs work and why they require specialized deployment strategies. A well-trained model alone is not enough—successful deployment depends on choosing the right infrastructure, optimizing performance, ensuring security, and maintaining scalability in production environments.
Kubernetes helps manage and scale containerized LLM deployments in production.
Link: Kubernetes → Kubernetes Documentation
Popular Large Language Models
Some of the most widely used Large Language Models include:
- GPT models
- Llama
- Claude
- Gemini
- Mistral
- Falcon
Unlike traditional machine learning models that are designed for a single task, Large Language Models can perform multiple language-based tasks using the same model. Their versatility makes them suitable for applications such as AI chatbots, virtual assistants, content generation, document summarization, code generation, customer support automation, and enterprise AI solutions.ecific task, LLMs can solve multiple language-related problems using a single model.
Key Capabilities of Large Language Models
Modern LLMs can perform numerous AI-powered tasks, including:
- Natural language understanding
- Text generation
- Content summarization
- Language translation
- Question answering
- Code generation
- Document analysis
- Sentiment analysis
- Customer support automation
- AI-powered search
These capabilities make LLMs valuable across industries such as healthcare, finance, education, legal services, retail, manufacturing, and software development.
Why Is LLM Deployment Important?
Why Is LLM Deployment Important?
Knowing how to deploy Large Language Model systems is essential for building AI applications that are scalable, secure, reliable, and high-performing. While training a Large Language Model requires significant time, expertise, and computational resources, its true value is realized only when it is successfully deployed into a production environment where users and applications can access it seamlessly.
Understanding how to deploy Large Language Model solutions helps organizations improve scalability, reduce latency, strengthen security, and deliver a better user experience. A well-planned deployment strategy ensures that AI models perform efficiently while meeting business and technical requirements.
Learning how to deploy Large Language Model applications correctly provides several key benefits:
- Faster AI response times
- Better scalability for growing workloads
- Lower infrastructure and operational costs
- Improved application reliability
- Enhanced security and data protection
- Higher user satisfaction and better customer experiences
A production-ready Large Language Model can be integrated into websites, mobile applications, enterprise software, APIs, customer support platforms, and internal business workflows. By following the right deployment practices, businesses can maximize the performance of their AI solutions while ensuring long-term scalability, security, and operational efficiency.
Understanding Large Language Model Deployment
Large Language Model deployment is the process of making a trained AI model available for real-world use. Instead of running only inside research environments, the model is deployed on servers, cloud platforms, or edge infrastructure where applications can send requests and receive AI-generated responses.
A typical deployment workflow includes:
- Selecting the appropriate LLM.
- Preparing the deployment environment.
- Optimizing the model for inference.
- Packaging the application.
- Deploying the model to production.
- Monitoring performance and scaling resources.
Understanding how to deploy Large Language Model systems effectively helps organizations deliver AI services that are fast, secure, reliable, and cost-efficient.
Deployment Challenges of Large Language Models
Although LLMs provide exceptional capabilities, deploying them in production presents several technical and operational challenges. Addressing these challenges is essential for ensuring optimal performance, scalability, and security.
Read More – hybrid deployment combines
1. High Computational Requirements
Large Language Models contain millions or even billions of parameters, requiring powerful hardware such as GPUs, TPUs, or AI accelerators for efficient inference.
Organizations must carefully plan infrastructure based on:
- GPU availability
- CPU performance
- Memory requirements
- Storage capacity
- Network bandwidth
Without adequate computing resources, response times can increase significantly.
2. Latency and Response Time
Users expect AI applications to respond within seconds.
Reducing inference latency is one of the biggest challenges when learning how to deploy Large Language Model applications. Slow response times can negatively affect customer satisfaction and business productivity.
Latency optimization often involves:
- Model quantization
- GPU acceleration
- Request batching
- Efficient APIs
- Intelligent caching
3. Large Model Size
Modern LLMs can occupy several gigabytes—or even hundreds of gigabytes—of storage.
Large models increase:
- Storage costs
- Loading time
- Memory usage
- Deployment complexity
Techniques such as pruning, quantization, and knowledge distillation help reduce model size while maintaining acceptable accuracy.
4. Scalability Challenges
As application traffic increases, AI infrastructure must scale efficiently without compromising performance.
A scalable deployment architecture should support:
- Auto scaling
- Load balancing
- Multiple inference servers
- Distributed computing
- High availability
Cloud-native deployment platforms are commonly used to handle fluctuating workloads.
5. Security and Privacy
Security is one of the most important considerations during LLM deployment.
Organizations must protect:
- User prompts
- Sensitive enterprise data
- API endpoints
- Model access
- Stored conversations
Best security practices include:
- End-to-end encryption
- Role-based access control (RBAC)
- API authentication
- Secure cloud environments
- Continuous security monitoring
6. Infrastructure Cost
Running powerful GPUs continuously can become expensive.
Businesses must balance:
- Performance
- Infrastructure costs
- Model accuracy
- Resource utilization
Choosing the right deployment architecture significantly impacts the overall return on investment (ROI).
7. Monitoring and Maintenance
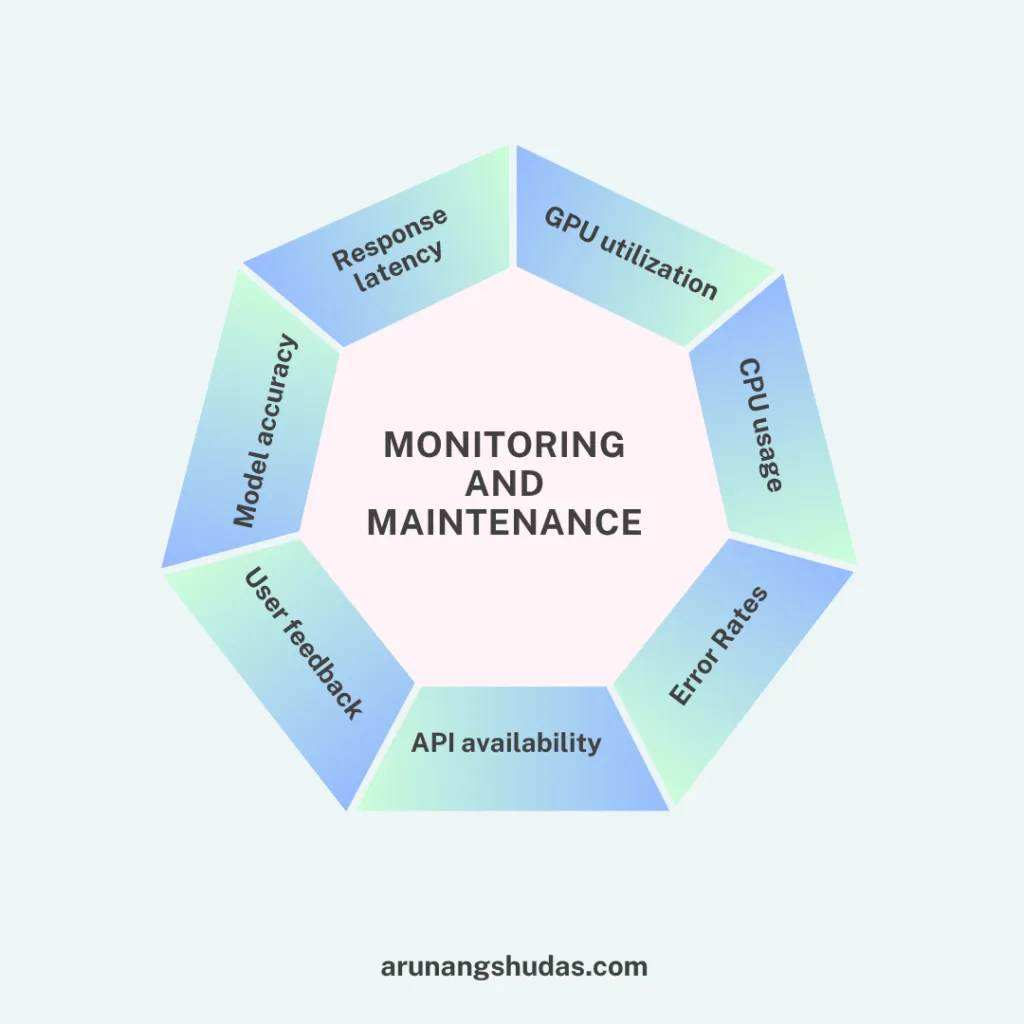
Deploying an LLM is not a one-time task. Continuous monitoring is required to maintain optimal performance.
Key metrics include:
- Response latency
- GPU utilization
- CPU usage
- Error rates
- API availability
- User feedback
- Model accuracy
Regular updates and performance optimization ensure the deployed model continues to deliver reliable AI experiences.
How to Deploy Large Language Model: Step-by-Step Deployment Strategies
Successfully learning how to deploy Large Language Model applications requires selecting the right deployment strategy based on your infrastructure, budget, scalability requirements, and security needs. Below are the most effective deployment approaches used by modern organizations.
1. Cloud-Based Deployment
Cloud deployment is one of the most popular methods for deploying Large Language Models because it offers scalability, flexibility, and managed infrastructure.
Popular cloud providers include:
- Amazon Web Services (AWS)
- Microsoft Azure
- Google Cloud Platform (GCP)
Advantages
- Easy deployment
- Auto scaling
- Managed GPU infrastructure
- High availability
- Global accessibility
Best For
- SaaS applications
- Enterprise AI
- Chatbots
- Customer support systems
2. On-Premises Deployment
Organizations handling sensitive or regulated data often deploy Large Language Models within their own infrastructure.
Advantages
- Complete data privacy
- Better compliance
- Full infrastructure control
- Reduced third-party dependency
Best For
- Healthcare
- Banking
- Government
- Defense
3. Hybrid Deployment
A hybrid deployment combines cloud computing with on-premises infrastructure.
For example:
- Sensitive customer data remains on local servers.
- AI inference and analytics run in the cloud.
This approach balances security, performance, and scalability.
4. Edge Deployment
Edge deployment places the model closer to end users, reducing latency and improving real-time performance.
Common use cases include:
- Smart devices
- IoT applications
- Autonomous vehicles
- Industrial automation
Comparison Table: LLM Deployment Strategies
| Deployment Strategy | Best For | Advantages | Challenges |
|---|---|---|---|
| Cloud Deployment | Enterprise AI Applications | High scalability, managed infrastructure | Ongoing cloud costs |
| On-Premises Deployment | Regulated Industries | Maximum security and privacy | High hardware investment |
| Hybrid Deployment | Large Enterprises | Balanced performance and security | Complex architecture |
| Edge Deployment | Real-Time AI Applications | Ultra-low latency | Limited computing resources |
Read More – AI infrastructure
Model optimization reduces the compute footprint and memory bandwidth required during inference, directly improving Time to First Token (TTFT), Time Per Output Token (TPOT), and server throughput. Production LLM optimization spans three core layers: weight compression, architectural/memory management, and runtime pipeline acceleration.
1. Model Compression Techniques
- Quantization (Weight & Activation Reduction):
- Post-Training Quantization (PTQ): Converts FP16/BF16 weights to lower precision (FP8, INT8, or INT4) without re-training.
- AWQ (Activation-aware Weight Quantization) & GPTQ: Protects salient weight channels based on activation patterns, achieving 2–4x memory footprint reduction with negligible (<1%) perplexity loss.
- FP8 Precision: Supported natively on modern GPU architectures (e.g., NVIDIA Hopper/Ada Lovelace), offering up to 2x matrix multiplication throughput while maintaining full numerical stability.
- Knowledge Distillation:
- Transfers knowledge from a large “teacher” model (e.g., 70B+) into a compact “student” model (e.g., 8B) by training on the teacher’s soft probability distributions.
- Permanently lowers inference latency and hardware requirements while retaining high performance on specific target domains.
- Pruning (Structured vs. Unstructured):
- Removes redundant parameters, attention heads, or entire transformer layers that contribute minimally to task accuracy.
- Structured Pruning is preferred in production because it alters matrix dimensions into smaller uniform shapes that yield direct hardware acceleration without requiring sparse tensor kernels.
2. Attention & Memory Architecture Optimizations
- PagedAttention & KV Cache Management:
- Eliminates GPU memory fragmentation by allocating Key-Value (KV) cache memory in dynamic, virtual-memory style pages.
- Increases maximum batch sizes by 2–4x by eliminating over-allocation and static sequence padding.
- FlashAttention (v2/v3):
- Re-engineers attention mechanisms to compute softmax tiling in GPU SRAM rather than High Bandwidth Memory (HBM).
- Eliminates $O(N^2)$ memory read/write bottlenecks, delivering 2–5x speedups on long-context prefill phases.
- Grouped-Query Attention (GQA):
- Shares key and value heads across multiple query heads, cutting KV cache memory overhead by 4–8x compared to traditional Multi-Head Attention (MHA).
- Speculative Decoding (e.g., EAGLE-2, Medusa):
- Employs a lightweight draft model or extra feature heads to propose $K$ candidate tokens in parallel, which the main model verifies in a single forward pass.
- Speeds up sequential token generation by 2–3x without altering the mathematically exact output distribution of the primary model.
3. Runtime Acceleration & Serving Pipeline
- Continuous Batching (In-Flight Batching):
- Dynamically inserts new incoming queries and evicts completed sequences at iteration boundaries rather than waiting for an entire static batch to finalize.
- Saturates GPU utilization and multiplies overall request throughput by 5–20x.
- Prefill vs. Decode Disaggregation:
- Splits compute-heavy prompt processing (prefill phase) and memory-bandwidth-bound token generation (decode phase) onto dedicated, independently auto-scaled GPU node pools.
- Model Parallelism:
- Tensor Parallelism (TP): Splits individual matrix multiplications across GPUs within the same node over high-speed NVLink interconnects.
- Pipeline Parallelism (PP): Partition model layers sequentially across nodes for massive models exceeding multi-GPU memory limits.
Conclusion
Understanding how to deploy Large Language Model solutions is essential for organizations looking to build scalable, secure, and production-ready AI applications. From selecting the right deployment strategy to optimizing infrastructure and monitoring performance, every stage of deployment plays a critical role in delivering reliable AI experiences.
Cloud deployment provides flexibility and scalability, on-premises deployment offers maximum security, hybrid deployment balances both worlds, and edge deployment enables real-time AI applications with ultra-low latency. Choosing the right approach depends on your business objectives, compliance requirements, infrastructure, and expected workload.
As Large Language Models continue to evolve, businesses that adopt best practices, optimize model performance, and implement secure deployment architectures will gain a competitive advantage. By following the strategies outlined in this guide, you can successfully deploy Large Language Models that deliver faster responses, lower operational costs, improved scalability, and exceptional user experiences
Frequently Ask Questions –
How do you deploy a Large Language Model?
Deploying a Large Language Model involves selecting the model, preparing infrastructure, optimizing inference, containerizing the application, deploying it to production, and continuously monitoring performance.
Which cloud platform is best for LLM deployment?
AWS, Microsoft Azure, and Google Cloud Platform are among the most popular platforms because they provide scalable GPU infrastructure and managed AI services.
Can Large Language Models run on local servers?
Yes. Organizations can deploy open-source Large Language Models on local servers using GPUs for greater security, compliance, and data privacy.
What is the biggest challenge in LLM deployment?
The biggest challenges include high computational requirements, infrastructure costs, latency optimization, scalability, and protecting sensitive user data.
Why is optimization important before deploying a Large Language Model?
Optimization techniques such as quantization, pruning, and efficient inference reduce hardware costs, improve response times, and enhance overall application performance.
