

In machine learning, the quality and quantity of data play pivotal roles in the performance of models. However, obtaining large, diverse, and labeled datasets can be a challenging task. This is where data augmentation comes into play, offering a powerful solution to enhance the training data by generating synthetic samples.
Understanding Data Augmentation
Data augmentation is a technique commonly used in computer vision and natural language processing tasks. It involves applying a variety of transformations to the existing data to create new instances that are similar but not identical to the original samples. These transformations maintain the inherent characteristics of the data while introducing variations, thereby enriching the dataset and making the model more robust.
Benefits of Data Augmentation
- Increased Robustness: By exposing the model to diverse variations of the input data during training, data augmentation helps improve the model’s ability to generalize to unseen examples.
- Reduced Overfitting: Augmented data introduces noise and variability, which can prevent the model from memorizing the training examples and, consequently, reduce overfitting.
- Improved Performance: With a larger and more varied dataset, machine learning models often achieve better performance metrics such as accuracy and generalization.
Image Data Augmentation
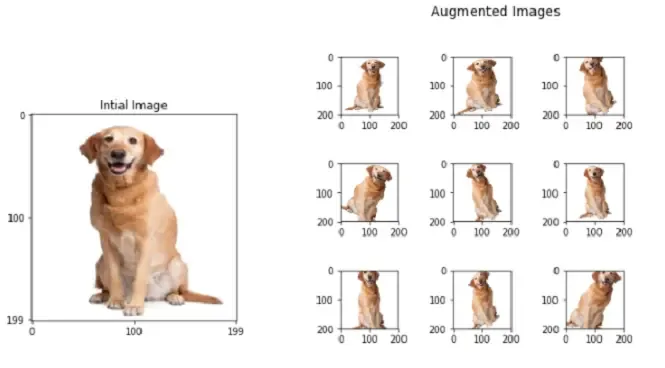
Image data augmentation introduces geometric, photometric, and noise-based variations into visual datasets, teaching convolutional neural networks (CNNs) and vision transformers (ViTs) to achieve spatial and photometric invariance.
- Rotation:
- Mechanism: Rotates the input image along its central axis by a defined angle (e.g., between $-30^\circ$ and $+30^\circ$).
- Use Case: Crucial for objects where orientation does not alter identity, such as satellite imagery, cell microscopy, or manufacturing defect inspection.
- Caution: Avoid on orientation-sensitive tasks like optical character recognition (OCR) or digit recognition where a $180^\circ$ rotation turns a
6into a9.
- Translation (Spatial Shifting):
- Mechanism: Shifts the pixel matrix along the horizontal (X) or vertical (Y) axes by a specified fraction or pixel count, padding exposed edges via zero-filling, reflection, or nearest-neighbor wrapping.
- Use Case: Prevents models from developing positional bias when objects predominantly appear centered in raw training data.
- Scaling (Zoom In / Zoom Out):
- Mechanism: Scales the resolution of the image upward (cropping outward bounds) or downward (padding perimeter bounds).
- Use Case: Trains object detectors (e.g., YOLO) to recognize subjects regardless of distance from the camera lens.
- Flipping (Mirroring):
- Mechanism: Inverts the pixel array across the vertical axis (horizontal flip) or horizontal axis (vertical flip).
- Use Case: Horizontal flipping is standard for general object detection (vehicles, animals, scenery). Vertical flipping is applied to aerial imagery, astronomy, and pathology slides.
- Noise Injection (Gaussian / Salt-and-Pepper):
- Mechanism: Adds random high-frequency pixel variations drawn from a statistical distribution (e.g., zero-mean Gaussian distribution).
- Use Case: Functions as implicit regularization, forcing neural networks to prioritize macro-level edge contours over fragile high-frequency pixel patterns.
- Color Jittering:
- Mechanism: Randomly modifies photometric properties: brightness (exposure), contrast (dynamic range), saturation (color intensity), and hue (color spectrum shift).
- Use Case: Essential for autonomous driving and outdoor surveillance, ensuring accurate classification across varying daylight, shadow, and weather conditions.
Text Data Augmentation (EDA – Easy Data Augmentation)
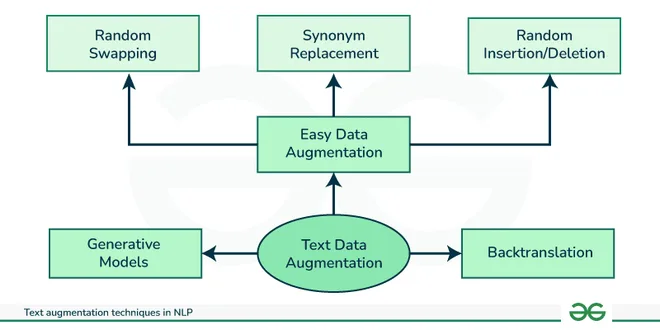
Because natural language relies on discrete tokens and strict syntax, NLP augmentation modifies token placement and semantics without altering ground-truth labels.
- Synonym Replacement (SR):
- Mechanism: Randomly selects $n$ non-stop words from a sentence and replaces them with corresponding synonyms using a lexical database (like WordNet) or contextual embeddings (like Word2Vec/GloVe).
- Example: “The fast car accelerated quickly.” $\rightarrow$ “The rapid car accelerated quickly.”
- Benefit: Expands model vocabulary coverage across semantically equivalent phrasing.
- Random Insertion (RI):
- Mechanism: Finds a random non-stop word in the sentence, identifies a synonym, and inserts that synonym into a completely random index within the sentence $n$ times.
- Example: “The team won the championship.” $\rightarrow$ “The team won the victory championship.”
- Benefit: Simulates conversational speech patterns and natural padding, training sequence models to isolate core semantic intent despite extraneous tokens.
- Random Deletion (RD):
- Mechanism: Iterates through every word in a sequence and deletes it with a fixed probability $p$ (typically $p \in [0.05, 0.2]$).
- Example: “Please ensure you validate all incoming API payloads.” $\rightarrow$ “Please ensure you validate all API payloads.”
- Benefit: Similar to dropout at the input layer; teaches transformers and recurrent models to retain contextual meaning when words are missing or truncated.
- Random Swap (RS):
- Mechanism: Randomly selects two words at different positions in the sentence and swaps their locations. This process is repeated $n$ times.
- Example: “Send the report by morning.” $\rightarrow$ “Report the send by morning.”
- Benefit: Reduces sensitivity to strict word order dependencies, making classification and sentiment analysis models resilient to typos and colloquial grammatical variations.
Implementing Data Augmentation
Let’s take a look at a simple Python code snippet demonstrating image data augmentation using the popular library Keras with ImageDataGenerator.
from keras.preprocessing.image import ImageDataGenerator
from keras.datasets import mnist
import numpy as np

# Load MNIST dataset
(x_train, y_train), (x_test, y_test) = mnist.load_data()

# Reshape and normalize images
x_train = x_train.reshape(-1, 28, 28, 1).astype('float32') / 255
x_test = x_test.reshape(-1, 28, 28, 1).astype('float32') / 255

# Create an ImageDataGenerator instance
datagen = ImageDataGenerator(
    rotation_range=20,
    width_shift_range=0.1,
    height_shift_range=0.1,
    shear_range=0.2,
    zoom_range=0.2,
    horizontal_flip=True,
    fill_mode='nearest'
)

# Fit the generator on the training data
datagen.fit(x_train)

# Generate augmented data
augmented_data = datagen.flow(x_train, y_train, batch_size=32)

# Example of using augmented data in model training
model.fit(augmented_data, epochs=10, validation_data=(x_test, y_test))
In this code, we use ImageDataGenerator to define various augmentation parameters such as rotation, width and height shift, shear range, zoom range, and horizontal flipping. Then, we fit the generator on the training data and generate augmented batches of data for model training.
Conclusion
Data augmentation is a powerful technique to enhance the performance and robustness of machine learning models, particularly when dealing with limited or imbalanced datasets. By introducing diverse variations to the training data, models can learn to generalize better and achieve improved performance on unseen examples.
Read more blog : AI vs Human Creativity: Who Wins in the Long Run?
Frequently Ask Question:
1. Does data augmentation replace the need for collecting real data?
No. While data augmentation significantly improves dataset diversity and helps combat overfitting, synthetic transformations cannot entirely replace authentic real-world data distributions and edge cases. It is an enrichment technique rather than a complete replacement for diverse real-world sampling.
2. Can data augmentation degrade model performance?
Yes, if inappropriate transformations are applied that alter ground-truth labels. For example, applying horizontal or vertical flips on digit datasets (such as turning a ‘6’ into a ‘9’ or an inverted ‘6’) or applying extreme color shifts on color-dependent classification tasks will inject noisy, incorrect labels and reduce accuracy.
3. Should data augmentation be applied to the test or validation datasets?
Generally, no. Augmentations should only be applied to the training dataset. Validation and test sets must represent unmodified, true real-world inputs to accurately evaluate how well the model generalizes. (An exception is Test-Time Augmentation (TTA), where multiple augmented versions of a single test image are evaluated and averaged for ensembled inference).
4. How does text augmentation differ in difficulty from image augmentation?
Text augmentation is generally more delicate because minor modifications (like swapping or deleting words) can distort grammar, syntax, and underlying semantic meaning. Computer vision transformations like small rotations or brightness shifts rarely alter an image’s fundamental class, whereas replacing a single word with an imperfect synonym can invert sentiment or change context completely.
