

Databases are the backbone of almost every modern application, from small websites to massive enterprise systems. However, as data grows, so does the challenge of retrieving it efficiently. That’s where database indexing comes into play.
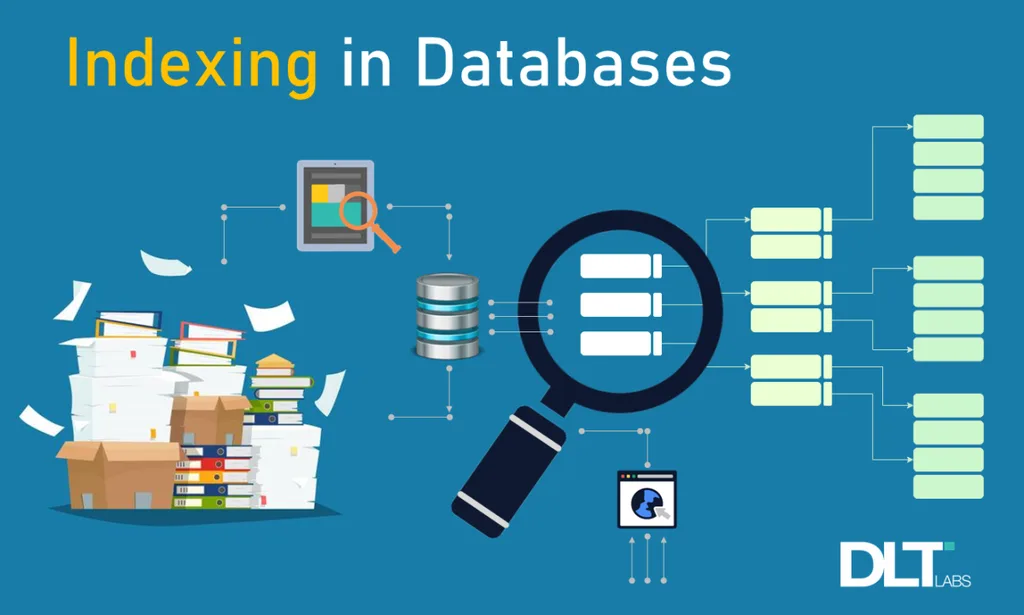
An index is a data structure that improves the speed of data retrieval operations at the cost of additional storage and maintenance overhead. Think of it like an index in a book—it helps you quickly find what you’re looking for without scanning every page.
1. Clustered Index (Primary Index)
A clustered index determines the physical order of data rows on disk. Because table rows can only be arranged in one physical sequence, a table can contain only one clustered index.
- Underlying Mechanism: The database builds the index directly into the leaf nodes of the table’s primary storage structure (typically a B+ Tree). In systems like MySQL (InnoDB), the primary key automatically acts as the clustered index.
- SQL Implementation:
SQL
-- Automatically created via primary key
CREATE TABLE employees (
    employee_id INT PRIMARY KEY,
    full_name VARCHAR(100),
    department VARCHAR(50)
);
- Best Used For: High-volume range scans (
BETWEEN,>,<) and queries retrieving sequential data such as date-ordered logs or continuous IDs. - Trade-offs: Significant write overhead. Inserting a record with an arbitrary key requires physical page splits to maintain order, slowing down
INSERTandUPDATEoperations.
2. Non-Clustered Index (Secondary Index)
A non-clustered index stores index keys alongside pointers (row locators or primary key values) that point to the physical storage location of the row data, leaving the table’s underlying row order unchanged.
- Underlying Mechanism: A completely separate structure from the main table. When queried, the engine scans the non-clustered index to find the pointer, then performs a lookup (bookmark lookup) to fetch the remaining row data.
- SQL Implementation:
SQL
CREATE INDEX idx_employee_name ON employees(full_name);
- Best Used For: Speeding up search filters on foreign keys, secondary lookup columns, and fields frequently evaluated in
WHEREorJOINclauses. - Trade-offs: Consumes additional disk space and memory. Every write requires the database engine to maintain both the table data and each secondary index structure.
3. Unique Index
A unique index guarantees that no two rows contain identical values in the indexed column or composite column set.
- Underlying Mechanism: Operates similarly to a standard B-Tree non-clustered index, but adds an integrity constraint check at the storage engine level during data modification.
- SQL Implementation:
SQL
CREATE UNIQUE INDEX idx_user_email ON users(email);
- Best Used For: Enforcing natural business keys that must remain distinct across the system, such as email addresses, social security numbers, or usernames.
- Trade-offs: Adds latency to write paths because the storage engine must execute an index scan to verify uniqueness before committing an
INSERTorUPDATE.
Read more Blog : 10 Common Mistakes in Database Indexing
4. Bitmap Index
A bitmap index represents column values as arrays of bits (0s and 1s), mapping each bit position to a specific row ID.
- Underlying Mechanism: For each distinct value in a column, the engine creates a bit vector. Query filters run using rapid bitwise boolean operations (
AND,OR,NOT) directly at the CPU register level. - Bit Vector Representation:
| Row ID | Active | Inactive | Pending |
| 1 | 1 | 0 | 0 |
| 2 | 0 | 1 | 0 |
| 3 | 0 | 0 | 1 |
- Best Used For: Read-heavy data warehouses and OLAP workloads on low-cardinality columns (e.g., status flags, regions, boolean fields).
- Trade-offs: Unsuitable for high-concurrency OLTP applications. Modifying a single row often locks the entire bitmap segment, creating write contention. High-cardinality columns cause bitmap sizes to balloon.
5. B-Tree Index
The Balanced Tree (B-Tree and its variant, the B+ Tree) serves as the default indexing architecture across relational database management systems like PostgreSQL, MySQL, and Oracle.
- Underlying Mechanism: A multi-level self-balancing tree that keeps data sorted and provides consistent $O(\log n)$ search, insertion, and deletion times. Leaf nodes in B+ Trees are linked sequentially, making range traversals fast.
- SQL Implementation:
SQL
CREATE INDEX idx_orders_created ON orders(created_at);
- Best Used For: General-purpose query acceleration, exact-match equality filters (
=), range filters (BETWEEN,<,>=), and sort operations (ORDER BY). - Trade-offs: Memory footprint scales with table volume. High-write workloads trigger background tree rebalancing and page splits, leading to index fragmentation over time.
6. Hash Index
A hash index applies a cryptographic or non-cryptographic hash function to column values, mapping them to fixed-size buckets containing row pointers.
- Underlying Mechanism: Computes an exact hash key for the lookup value, yielding $O(1)$ constant-time retrieval.
- SQL Implementation:
SQL
-- PostgreSQL syntax
CREATE INDEX idx_user_token ON sessions USING HASH (session_token);
- Best Used For: Direct key-value lookups (
WHERE token = 'xyz') in memory-optimized tables or caching layers. - Trade-offs: Does not support range evaluations (
>,<,BETWEEN), pattern matching (LIKE 'abc%'), or ordering (ORDER BY). Hash collisions degrade search speed to linear scans within the target bucket.
7. Full-Text Index
A full-text index builds an inverted index that breaks text fields into individual tokens, stems them to their root form, and tracks their frequency and position across records.
- Underlying Mechanism: Maps individual keywords to the list of documents containing them, bypassing costly full-table wildcard scans (
LIKE '%keyword%'). - SQL Implementation:
SQL
CREATE FULLTEXT INDEX idx_article_body ON articles(body_content);

-- Query execution
SELECT * FROM articles
WHERE MATCH(body_content) AGAINST('database optimization' IN NATURAL LANGUAGE MODE);
- Best Used For: Search bars, catalog searches, knowledge bases, and complex linguistic queries requiring relevance ranking or fuzzy matching.
- Trade-offs: Substantial disk storage and memory overhead. Text parsing, tokenization, and stop-word filtering significantly increase ingestion latency for new content.
Database Index Architecture Comparison
| Index Type | Time Complexity (Exact Match) | Range Query Support | Best Data Cardinality | Primary Workload Profile |
| Clustered | $O(\log n)$ | Yes (Optimal) | High | OLTP & OLAP (Sequential Reads) |
| Non-Clustered | $O(\log n)$ + Lookup | Yes | High | OLTP (Filtered Lookups) |
| Unique | $O(\log n)$ | Yes | Maximum (Distinct) | Data Integrity Enforcement |
| Bitmap | $O(1)$ (Bitwise) | No | Very Low | OLAP / Analytics Data Warehouses |
| B-Tree | $O(\log n)$ | Yes | Moderate to High | General OLTP Workloads |
| Hash | $O(1)$ | No | High | Exact Match Caching / Lookups |
| Full-Text | Variable | No (Keyword-based) | Unstructured Text | Search Engines & |
Mastering Database Indexing for High-Performance Architectures
Optimizing database performance is an exercise in balancing read velocity against write throughput and storage footprint. While indexes like B-Trees and clustered structures accelerate range scans and equality lookups, excessive or unmonitored indexing triggers severe write amplification, frequent page splits, and cache bloat in production environments.
Building a scalable data tier requires engineering teams to continuously profile real-world execution plans using tools like EXPLAIN ANALYZE, identify unindexed foreign keys, and retire redundant secondary indexes. Aligning each column’s unique cardinality and access patterns with the appropriate index architecture ensures reliable, sub-millisecond query execution even as data scales to billions of records.
You may also like:
1) 5 Common Mistakes in Backend Optimization
2) 7 Tips for Boosting Your API Performance
3) How to Identify Bottlenecks in Your Backend
4) 8 Tools for Developing Scalable Backend Solutions
5) 5 Key Components of a Scalable Backend System
6) 6 Common Mistakes in Backend Architecture Design
7) 7 Essential Tips for Scalable Backend Architecture
8) Token-Based Authentication: Choosing Between JWT and Paseto for Modern Applications
9) API Rate Limiting and Abuse Prevention Strategies in Node.js for High-Traffic APIs
10) Can You Answer This Senior-Level JavaScript Promise Interview Question?
11) 5 Reasons JWT May Not Be the Best Choice
12) 7 Productivity Hacks I Stole From a Principal Software Engineer
13) 7 Common Mistakes in package.json Configuration
Read more blogs from Here
Share your experiences in the comments, and let’s discuss how to tackle them!
Follow me on Linkedin
Frequently Asked Questions About Database Indexing
What is the main purpose of a database index?
A database index minimizes disk I/O and query latency by creating an ordered pointer structure that allows the query engine to locate records without executing a full-table scan. By organizing data keys into searchable structures like B-Trees or hash tables, indexes reduce search complexity from linear time, $O(n)$, down to logarithmic time, $O(\log n)$, or constant time, $O(1)$.
What is the difference between a clustered and non-clustered index?
The core difference lies in how data is physically stored on disk:
Clustered Index: Dictates the physical storage order of the actual table rows. Because data can only be physically stored in one sequence, a table can have only one clustered index (typically the Primary Key).
Non-Clustered Index: Stores a separate structure containing index keys along with row pointers (row locators) back to the original data. A table can have multiple non-clustered indexes.
Why do database indexes slow down write operations?
Every INSERT, UPDATE, or DELETE operation requires the database engine to modify both the primary table data and all corresponding secondary index trees. High index counts lead to:
Write Amplification: A single row write triggers multiple disk writes across different index pages.
Page Splits: Inserting values into a full index leaf node forces the engine to split pages and rebalance the tree structure.
Lock Contention: Modifying index structures creates locking overhead, reducing concurrent write throughput in OLTP workloads.
When should you avoid adding an index to a column?
Indexes should be avoided on:
Low-Cardinality Columns in OLTP: Columns with very few distinct values (such as boolean flags or status codes) where the query optimizer prefers a sequential scan over random disk seeks.
High-Churn Write Tables: Heavy log ingestion or telemetry tables where the overhead of maintaining index trees degrades ingestion throughput.
Small Tables: Datasets spanning only a few disk pages, where reading the entire table directly into memory is faster than traversing an index hierarchy.
Columns Rarely Used in Filtering: Fields that are never evaluated inside WHERE, JOIN, ORDER BY, or GROUP BY clauses.
