

Optimizing for Intent: How BERT Revolutionizes Natural Language Processing and Modern Search Understanding human language has always been one of the toughest challenges in computer science. Traditional algorithms often scanned text word-by-word, missing crucial nuances, slang, and contextual meaning.
Everything changed with the introduction of BERT (Bidirectional Encoder Representations from Transformers). Developed by Google researchers in 2018, BERT stands as a monumental shift in Natural Language Processing (NLP). By looking at words in relation to all surrounding words simultaneously, BERT unlocked a deeper, human-like understanding of context.
What is BERT and How Does It Work?
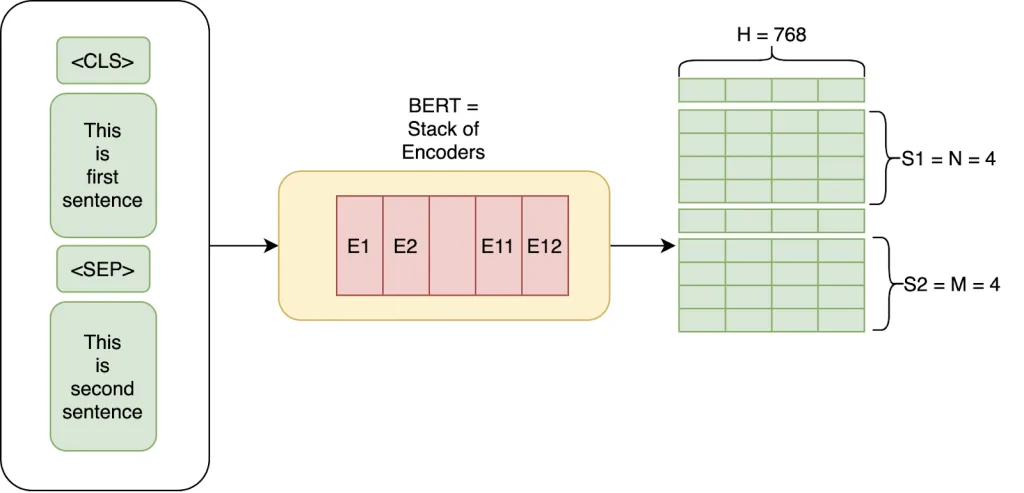
Unlike its predecessors—which processed text sequentially from left-to-right or right-to-left—BERT employs a bidirectional transformer architecture. This design captures contextual information from both left and right contexts in a sentence simultaneously.
For example, consider the word “bank.” In the phrases “financial bank account” versus “river bank mud,” BERT reads the entire sentence context to instantly differentiate the meaning.
Practical Implementation: Text Classification with BERT
Here is a foundational example showing how developers load a pre-trained BERT model using Python and PyTorch for sequence classification tasks:
Python
# Install the transformers library if you haven't already
# pip install transformers

import torch
from transformers import BertTokenizer, BertForSequenceClassification

# Load pre-trained BERT model and tokenizer
tokenizer = BertTokenizer.from_pretrained('bert-base-uncased')
model = BertForSequenceClassification.from_pretrained('bert-base-uncased')

# Define a sample text for classification
text = "BERT is an amazing tool for natural language processing tasks."

# Tokenize the input text
inputs = tokenizer(text, return_tensors='pt')

# Perform classification
outputs = model(**inputs)

# Get the predicted class
predicted_class = torch.argmax(outputs.logits).item()

# Define a mapping of class labels
class_labels = ['Negative', 'Neutral', 'Positive']  # Assuming 3 classes for classification

# Print the predicted class label
print("Predicted class:", class_labels[predicted_class])
Key Execution Steps:
- Import Libraries: Load PyTorch (
torch) alongsideBertTokenizerandBertForSequenceClassificationfrom Hugging Face’stransformerslibrary. - Load Pre-trained Weights: Initialize the
bert-base-uncasedmodel and tokenizer using.from_pretrained(). - Define and Tokenize Input: Process the sample text string into token tensors that the model can interpret.
- Model Inference: Pass tokenized inputs forward to obtain output logits, extracting the maximum probability index via PyTorch’s
torch.argmax()function.
Read More Blog : The Convergence of NLP and AI: Enhancing Human-Machine Communication
Core Features of BERT
- Bidirectional Contextual Understanding: Grasping word meanings dynamically based on immediate preceding and succeeding phrasing.
- Pre-training and Fine-tuning: Pre-trained on massive text corpora via unsupervised learning tasks, then fine-fitted for specific downstream applications.
- Transformer Architecture: Leverages multi-head self-attention mechanisms to allow parallel processing, drastically boosting computational efficiency.
Real-World Applications of BERT
- Sentiment Analysis: Discerning emotional tones (positive, neutral, or negative) across customer reviews, feedback forms, and social media posts.
- Question Answering (QA): Parsing dense reference texts to extract precise, contextually accurate answers for search queries or chat bots.
- Named Entity Recognition (NER): Automatically isolating and categorizing proper nouns such as individuals, companies, and geographical locations.
- Advanced Language Translation: Preserving semantic context across multi-lingual machine translation pipelines.
BERT vs. Traditional NLP Models: A Comparison
| Feature / Dimension | Traditional NLP Models (RNN / LSTM) | BERT Architecture |
| Processing Direction | Unidirectional (Left-to-Right or Right-to-Left) | Fully Bidirectional (Simultaneous left and right context) |
| Architecture | Recurrent Neural Networks (Sequential processing) | Transformer-based (Self-attention & parallelization) |
| Handling Ambiguity | Struggles with words having multiple meanings based on sentence structure | Excellent contextual disambiguation |
| Training Efficiency | Slower training times due to sequential token dependency | Highly scalable and efficient training via parallel computing |
Conclusion: Unlocking the Power of BERT for Modern NLP and Search
BERT (Bidirectional Encoder Representations from Transformers) has fundamentally changed the landscape of natural language processing and modern search engine optimization. By replacing outdated, unidirectional algorithms with a fully bidirectional transformer framework, BERT enables computers to understand sentence context, search intent, and linguistic nuances with human-like accuracy.
Frequently Asked Questions (FAQs)
What makes BERT different from older language models?
Older models process text sequentially in a single direction (either left-to-right or right-to-left). BERT uses a bidirectional transformer framework, meaning it evaluates a word’s context using both its left and right neighbors simultaneously.
How does BERT impact modern SEO and search engines?
BERT helps search engines like Google interpret search intent behind conversational and long-tail queries rather than matching isolated keywords, rewarding creators who write natural, high-quality content.
Can BERT be customized for specific industry niches?
Yes. BERT utilizes a two-step approach: massive general-purpose pre-training followed by task-specific fine-tuning on targeted datasets (such as legal, medical, or e-commerce texts).
What are the primary hardware limitations when running BERT?
Because BERT models contain millions or billions of parameters, they require significant computational resources, often necessitating high-performance GPUs or TPUs for efficient training and inference.
How does BERT assist in Generative Engine Optimization (GEO)?
By structuring content around natural intent, clear definitions, and semantic depth, content optimized with contextual clarity is more easily parsed, cited, and referenced by AI search summaries and generative engines.
