

Unsupervised learning and deep learning are transforming how we process raw, unlabeled data by extracting meaningful insights, structures, and patterns. Unlike supervised learning—where algorithms learn from explicit, human-labeled examples—unsupervised learning models must independently discern inherent patterns and data relationships. This autonomy makes unsupervised learning indispensable in modern data science, especially when labeled datasets are scarce, expensive, or entirely unavailable.
The Role of Deep Learning in Unsupervised Tasks
Deep learning, a specialized subset of machine learning inspired by the human brain, has revolutionized how we approach data science. By utilizing multilayered neural networks, deep learning models excel at capturing complex, hierarchical representations of information.
While traditional machine learning algorithms often plateau when handling high-dimensional or unstructured data, deep learning models thrive. Their ability to autonomously learn features makes them a natural fit for unsupervised learning tasks across various industries.
Read More : Recurrent Neural
Key Applications of Deep Learning in Unsupervised Learning
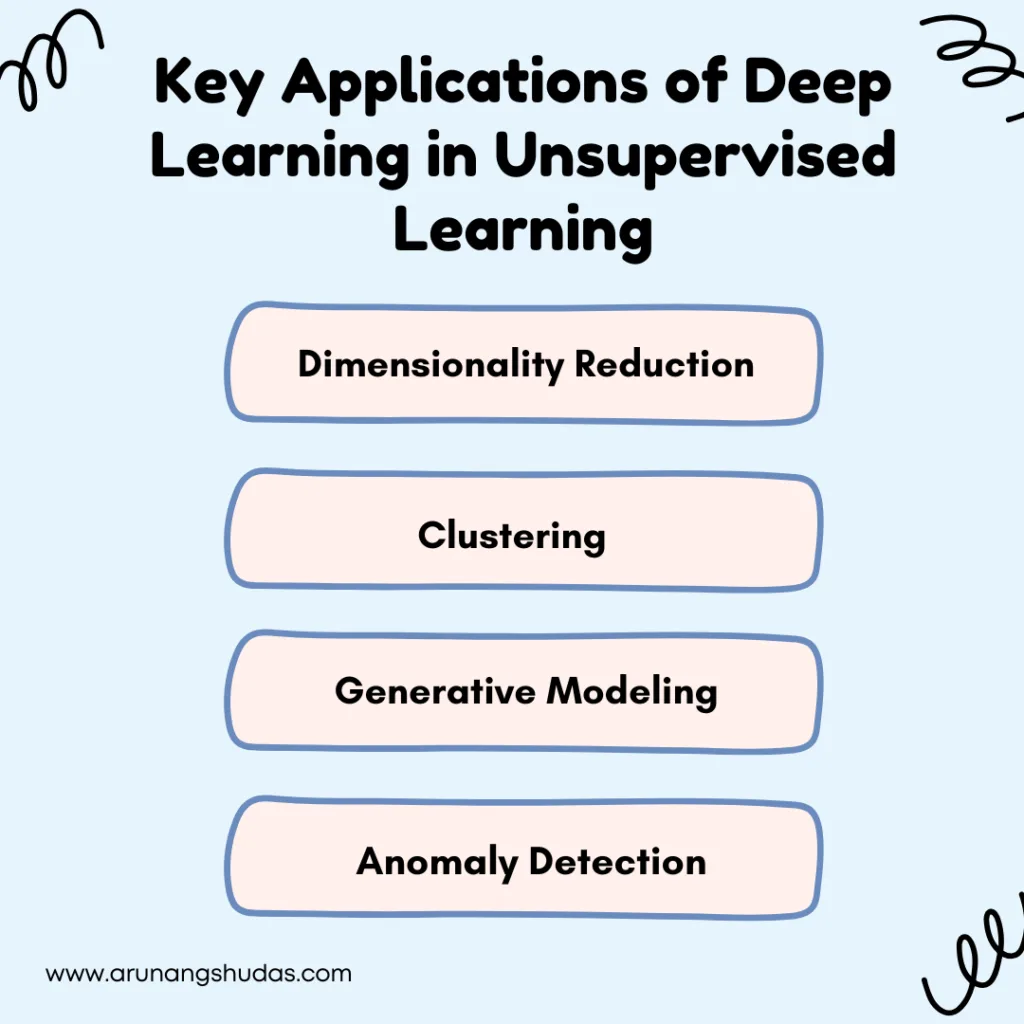
Deep learning powers several core unsupervised techniques that solve complex data challenges:
1. Dimensionality Reduction
High-dimensional data can overwhelm traditional analytical tools. Techniques like Autoencoders and Variational Autoencoders (VAEs) leverage deep learning to compress high-dimensional inputs into a lower-dimensional latent space while preserving vital features.
- Benefits: Facilitates efficient data visualization, noise reduction, and streamlined downstream analysis.
2. Clustering
Unsupervised clustering discovers hidden groups within unlabeled data. Deep clustering algorithms, such as Deep Embedded Clustering (DEC) and Deep Adaptive Image Clustering (DAIC), utilize neural networks to map data points and learn latent clusters simultaneously.
- Benefits: Iteratively updates network parameters and cluster assignments to foster highly accurate, scalable groupings.
3. Generative Modeling
Generative models synthesize brand-new data that mirrors a training dataset’s statistical properties.
- Generative Adversarial Networks (GANs): Pit a generator network against a discriminator network in a game-theoretic loop to synthesize hyper-realistic samples.
- Variational Autoencoders (VAEs): Learn to generate new instances by approximating the input data’s underlying probability distribution.
4. Anomaly Detection
Detecting rare events or irregularities is critical for system safety. Deep learning architectures like Recurrent Neural Networks (RNNs) and Autoencoders map the inherent structure of “normal” data behavior.
- Benefits: Instantly flags deviations or anomalies, bolstering fraud detection, cybersecurity monitoring, and industrial fault diagnosis.
Comparison: Key Unsupervised Deep Learning Techniques
| Application | Primary Deep Learning Models | Core Function / Objective | Typical Use Cases |
| Dimensionality Reduction | Autoencoders, VAEs | Compresses features into a lower-dimensional latent space | Data visualization, feature extraction |
| Clustering | DEC, DAIC | Discovers latent groupings within unlabeled data | Customer segmentation, image grouping |
| Generative Modeling | GANs, VAEs | Approximates data distribution to synthesize new data | Synthetic data generation, image-to-image translation |
| Anomaly Detection | Autoencoders, RNNs | Learns normal data distribution to isolate outliers | Fraud detection, network security, predictive maintenance |
Read More : Variational Autoencoders (VAEs)
Challenges and Considerations
Despite its immense capability, deploying deep learning for unsupervised learning comes with distinct hurdles:
Evaluation Metrics: Without ground truth labels, traditional validation metrics like accuracy and precision are inapplicable. Designing robust, objective evaluation frameworks for unsupervised outcomes remains challenging.
Data Efficiency: Deep learning models typically require massive volumes of data to generalize effectively. In data-scarce environments, unsupervised models may struggle to map underlying structures accurately.
Interpretability: The “black-box” nature of deep-layered neural networks makes it difficult to interpret how representations or cluster decisions are formed. Developing transparent, explainable architectures remains a major research focus.
Computational Resources: Training deep networks with millions of parameters demands intense computational power (GPUs/TPUs), making scale and cost significant management factors.
Conclusion: Mastering Unsupervised Learning with Deep Learning
In summary, the integration of advanced neural networks into unsupervised learning has unlocked unprecedented capabilities for extracting hidden structures from raw, unstructured data. By leveraging core techniques like dimensionality reduction, deep clustering, and generative modeling, organizations can transform untapped data repositories into actionable intelligence. However, successfully implementing deep learning for unsupervised tasks requires a careful balance—navigating compute demands, data efficiency, and interpretability hurdles while establishing robust, non-traditional evaluation frameworks. As architectures continue to evolve, mastering these unsupervised paradigms will remain a critical competitive edge for modern data scientists and AI practitioners alike.
Frequently Ask Questions :
What is the main difference between supervised and unsupervised deep learning?
Supervised deep learning relies on pre-labeled training datasets to map inputs to known outputs, whereas unsupervised deep learning algorithms work with completely unlabeled data, autonomously discovering patterns, structures, and groupings.
How do autoencoders work in unsupervised learning?
Autoencoders are neural networks designed to copy their inputs to their outputs. They feature a bottleneck layer (latent space) that forces the network to compress the data, stripping away noise and capturing only the most essential hierarchical features.
Why are GANs classified as unsupervised learning models?
Generative Adversarial Networks (GANs) do not require human-annotated labels. Instead, they learn the underlying probability distribution of a dataset entirely through self-supervised competition between a generator and a discriminator.
What are the primary business use cases for unsupervised deep learning?
Key commercial applications include customer segmentation (clustering), automated fraud detection (anomaly detection), recommendation systems, and synthetic data generation for privacy preservation.
How is the performance of an unsupervised deep learning model evaluated?
Because ground truth labels are absent, performance is typically measured using proxy metrics such as silhouette scores (for clustering), reconstruction error (for autoencoders), or domain-specific qualitative assessments for generative models.
