

In an age dominated by digital communication, the ability to comprehend and process human language is paramount. Natural Language Processing (NLP) stands at the forefront of this endeavor, wielding the power to analyze, understand, and generate human language in a way that machines can interpret. From virtual assistants to sentiment analysis, NLP permeates various aspects of our daily lives, revolutionizing how we interact with technology.
Understanding Natural Language Processing:
Natural Language Processing, a branch of artificial intelligence, focuses on the interaction between computers and human language. It encompasses a broad spectrum of tasks, ranging from basic text processing to advanced language understanding. NLP enables machines to comprehend the nuances of language, including syntax, semantics, and pragmatics, enabling them to interpret and generate human-like responses.
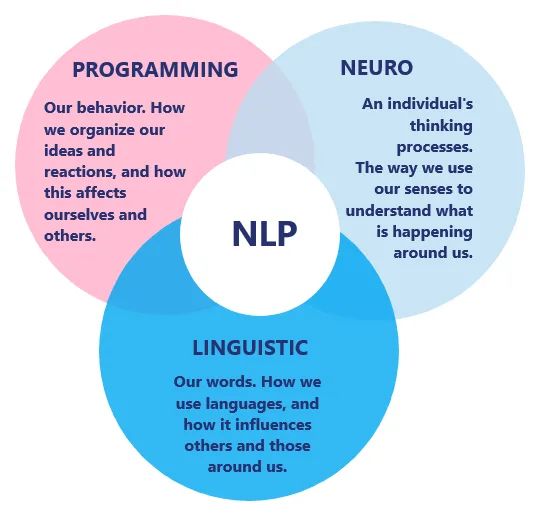
Core Techniques in Natural Language Processing (NLP)
Natural Language Processing (NLP) relies on a sequential pipeline of linguistic and statistical methods to transform unstructured text into machine-readable intelligence. The six foundational techniques below drive modern computational linguistics, search algorithms, and large language models.
1. Tokenization
Tokenization segments raw, unstructured text strings into smaller, discrete components called tokens—typically words, subwords, or punctuation marks.
- Primary Function: Establishes the initial baseline for computational parsing, vectorization, and model ingestion.
- Common Use Cases: Vocabulary construction, byte-pair encoding (BPE) for Large Language Models, text preprocessing pipelines.
2. Part-of-Speech (POS) Tagging
Part-of-Speech tagging evaluates the grammatical context of a sentence to assign syntactic markers—such as nouns, verbs, adjectives, and adverbs—to individual tokens.
- Primary Function: Resolves lexical ambiguity and decodes grammatical dependencies within sentences.
- Common Use Cases: Parsing engine inputs, voice assistant command routing, semantic relationship mapping.
3. Named Entity Recognition (NER)
NER locates and classifies predefined entities within unstructured text into explicit categories, including individuals, organizations, geographical locations, dates, and monetary values.
- Primary Function: Structures unstructured documents into queryable semantic data points.
- Common Use Cases: Automated knowledge graph construction, enterprise information retrieval, customer service ticket routing.
4. Sentiment Analysis
Sentiment analysis applies machine learning classifiers to determine the subjective tone and emotional polarity of a text, classifying expressions as positive, negative, neutral, or fine-grained emotional states.
- Primary Function: Quantifies human sentiment and customer perception at scale.
- Common Use Cases: Brand reputation monitoring, customer review scoring, algorithmic market research.
5. Machine Translation (MT)
Machine Translation uses deep learning architectures—primarily encoder-decoder Transformers—to automatically convert text between natural languages while preserving semantic context and tone.
- Primary Function: Enables cross-lingual communication without human intervention.
- Common Use Cases: Multilingual search indexation, localized customer support, real-time document localization.
6. Text Summarization
Text summarization condenses long-form text into high-signal, bite-sized summaries. Modern systems utilize either extractive summarization (extracting key sentences verbatim) or abstractive summarization (generating novel sentences that convey core themes).
- Primary Function: Maximizes information density while eliminating redundant prose.
- Common Use Cases: Automated search snippet generation, executive brief creation, academic abstract indexing.
Read more Blog : Role of NLP in AI-Based Sentiment Analysis
Comparison of Core NLP Techniques
| Technique | Level of Analysis | Primary Output | Real-World Application |
| Tokenization | Lexical | List of tokens/subwords | Search tokenization, LLM input pipelines |
| POS Tagging | Syntactic | Grammatically labeled tokens | Grammar checking, voice command parsing |
| NER | Semantic | Categorized named entities | Knowledge graphs, data extraction |
| Sentiment Analysis | Pragmatic | Polarity score or emotion class | Social listening, customer feedback analysis |
| Machine Translation | Cross-Lingual | Target-language text string | Global web localization, cross-border commerce |
| Text Summarization | Discourse | Concise content digest | Search engine overviews, research synthesis |
Real-World Applications of Natural Language Processing (NLP)
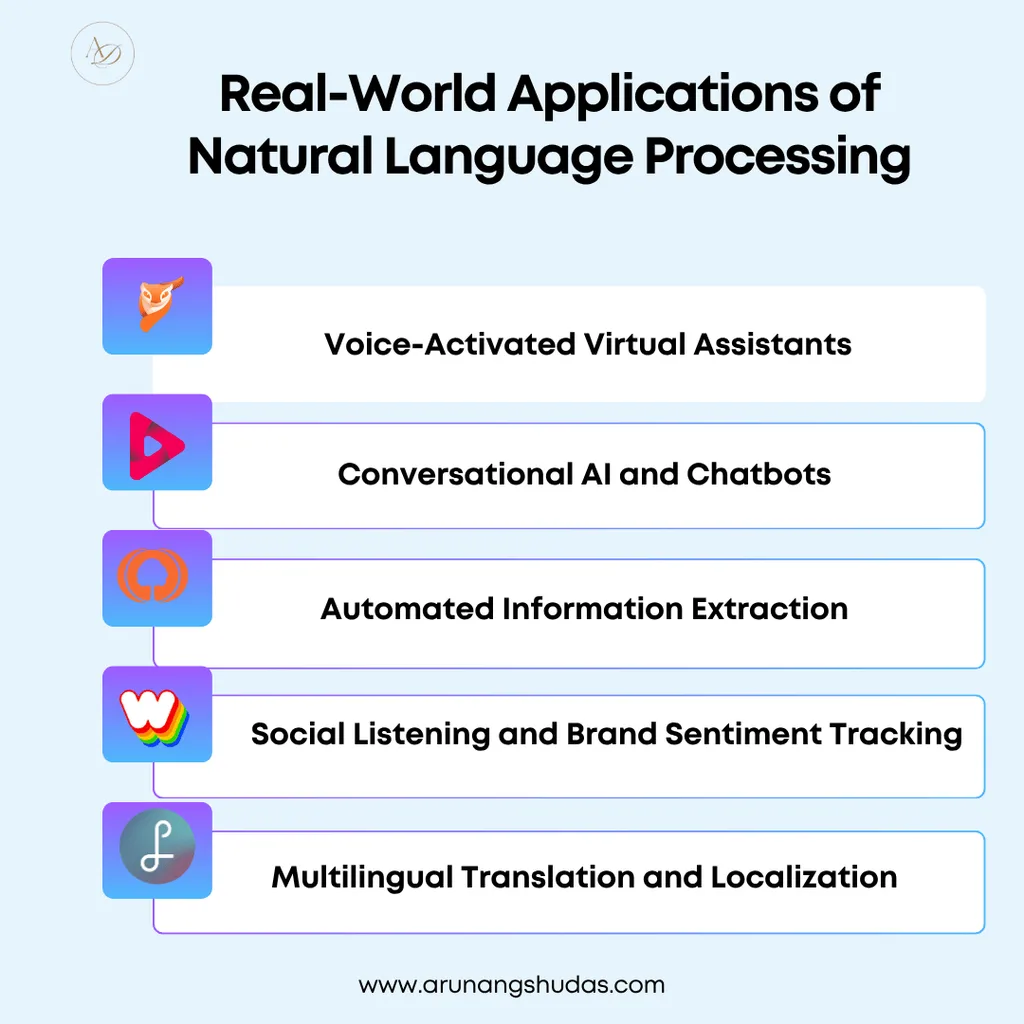
Natural Language Processing bridges the gap between human communication and computational logic. Modern organizations deploy NLP systems to automate high-volume operations, extract actionable intelligence from unstructured data, and power intelligent user interfaces.
1. Voice-Activated Virtual Assistants
Virtual assistants—including Siri, Alexa, and Google Assistant—combine Automatic Speech Recognition (ASR) with Natural Language Understanding (NLU) to interpret vocal intent and execute tasks.
- Core Functionality: Converts acoustic signals to text, extracts the underlying intent, and returns conversational or functional responses.
- Key Enterprise Impact: Enables hands-free IoT ecosystem management, smart home control, and frictionless in-car navigation.
2. Conversational AI and Chatbots
Enterprise chatbots use NLP to interpret contextual user input, resolve inquiries autonomously, and route complex edge cases to human agents.
- Core Functionality: Maintains dialogue state, queries back-end knowledge bases, and generates personalized responses in real time.
- Key Enterprise Impact: Scales 24/7 customer support, cuts mean response time (MRT), and qualifies inbound sales leads without increasing overhead.
3. Automated Information Extraction
Information extraction pipelines deploy Named Entity Recognition (NER), relation extraction, and text mining to convert unstructured textual corpora into structured databases.
- Core Functionality: Scans documents to identify key variables such as company names, dates, financial figures, and product attributes.
- Key Enterprise Impact: Accelerates regulatory compliance audits, streamlines contract review, and indexes competitor intelligence from market reports.
4. Social Listening and Brand Sentiment Tracking
Social media monitoring frameworks use sentiment analysis to process high-velocity user-generated content across public forums, review sites, and networks.
- Core Functionality: Quantifies subjective sentiment polarity (positive, neutral, negative) and tracks shifts in brand perception.
- Key Enterprise Impact: Flags PR crises in real time, measures campaign effectiveness, and identifies recurring product defects from user feedback.
5. Multilingual Translation and Localization
Machine translation systems leverage deep transformer models to translate digital content across hundreds of language pairs while preserving idioms, tone, and technical syntax.
- Core Functionality: Executes neural sequence-to-sequence translation adapted to specific domain glossaries.
- Key Enterprise Impact: Lowers internationalization costs for enterprise software, globalizes customer knowledge bases, and enables cross-border digital commerce.
NLP Application Matrix
| Application | Core NLP Technology | Primary Business Value | Typical Deployment |
| Virtual Assistants | ASR + Intent Recognition | Touchless interface & device control | Smart devices, mobile operating systems |
| Conversational Bots | NLU + Dialogue Management | Operational cost reduction at scale | Customer support portals, banking apps |
| Information Extraction | NER + Relation Extraction | Data structuring & workflow automation | Legal, healthcare records, finance |
| Social Listening | Sentiment Analysis + Aspect Mining | Brand reputation & risk management | Marketing analytics, PR tracking tools |
| Language Translation | Neural Machine Translation (NMT) | Global reach & localized user experience | Cross-border eCommerce, documentation |
Future Trends and Challenges:
- Advanced Language Models:
The development of large-scale language models, such as GPT (Generative Pre-trained Transformer) and BERT (Bidirectional Encoder Representations from Transformers), continues to push the boundaries of NLP. These models exhibit remarkable capabilities in understanding and generating human-like text, paving the way for more sophisticated applications. - Ethical Considerations:
As NLP technologies become more pervasive, ethical considerations surrounding data privacy, bias mitigation, and algorithmic transparency become increasingly important. Addressing these concerns is essential to ensure responsible and equitable deployment of systems. - Multimodal NLP:
The integration of multiple modalities, such as text, images, and audio, presents new opportunities and challenges in NLP. Multimodal NLP aims to develop models capable of understanding and generating content across different modalities, enabling more immersive and interactive user experiences.
The Future of Natural Language Processing
Natural Language Processing has transitioned from traditional syntactic rule-matching to an era dominated by large-scale transformer architectures, multimodal reasoning, and autonomous agentic workflows. As organizations integrate language models into production systems, NLP has shifted from an analytical backend tool into the primary interface for software interaction, semantic search, and enterprise automation.
Deploying these technologies effectively requires balancing computational efficiency with context-aware precision. Enterprises that combine foundational methods like tokenization and entity extraction with modern Retrieval-Augmented Generation (RAG) and specialized Small Language Models (SLMs) gain greater operational agility, defensible data privacy, and higher return on engineering investment.
Frequently Ask Question:
What is the difference between Natural Language Processing (NLP) and Natural Language Understanding (NLU)?
NLP is the overarching domain combining computational linguistics and computer science to help machines read, process, and generate human language. NLU is a specialized subfield within NLP focused specifically on extracting context, semantic intent, and meaning from text. While NLP handles mechanical tasks like tokenization and POS tagging, NLU determines the communicative objective behind the words.
How does modern NLP differ from traditional rule-based text processing?
Traditional NLP relied on manual rule sets, hand-crafted regular expressions, and rigid vocabulary dictionaries that often broke when encountering slang, misspellings, or varied sentence structures. Modern NLP uses deep learning models and self-attention transformers that analyze entire documents simultaneously, enabling systems to grasp nuanced semantics, idioms, and contextual dependencies without explicit rule programming.
What is the role of Named Entity Recognition (NER) in business intelligence?
NER automatically scans vast volumes of unstructured documents—such as contracts, news feeds, support tickets, and invoices—to extract and classify specific entities like organization names, geographic locations, dates, and currency values. This process structures raw text into relational records, accelerating automated compliance audits, market intelligence gathering, and CRM updates.
Can sentiment analysis detect complex human emotions such as sarcasm?
Modern sentiment analysis systems leverage contextual embeddings and transformer-based architectures that evaluate sentence context rather than just isolated positive or negative keywords. While older lexicon-based tools regularly misclassified sarcastic remarks, contemporary models detect syntactic contrast, tone shifts, and contextual contradictions with significantly higher accuracy.
Why is tokenization the most critical first step in an NLP pipeline?
Tokenization decomposes continuous text strings into discrete, numerical units (tokens) that machine learning architectures can process mathematically. If tokenization is inaccurate or handles subwords poorly, subsequent tasks—including part-of-speech tagging, entity recognition, and semantic parsing—fail to represent the intended linguistic relationships, degrading the entire pipeline.
