

In the ever-evolving landscape of deep learning, researchers are continually pushing the boundaries of what neural networks can achieve. Among the myriad of architectures and techniques, one stands out for its efficiency and effectiveness in handling complex visual data: the Inception Module and its eponymous network. Developed by researchers at Google, the Inception Module and its subsequent iterations have played a pivotal role in advancing the field of computer vision.
Understanding Inception Modules: Multi-Scale Feature Extraction
At the core of the Inception Network (GoogLeNet) lies the Inception Module—a fundamental building block engineered to extract features at multiple spatial scales efficiently.
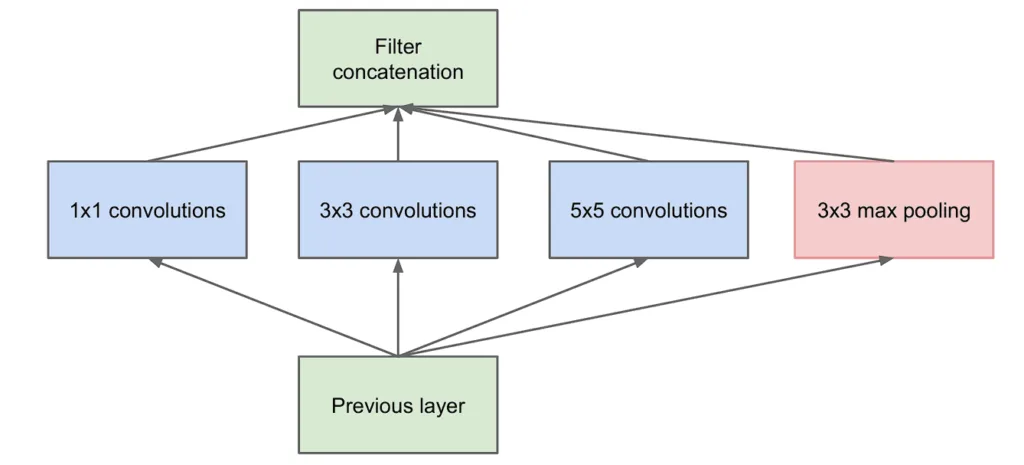
Unlike traditional convolutional networks that rely on fixed filter sizes per layer, the Inception Module applies parallel operations with varying receptive fields within a single layer. This multi-path design enables the network to process spatial features at different resolutions simultaneously.
1. The Core Architecture: Parallel Processing
In a standard Convolutional Neural Network (CNN), a designer must choose between filter sizes (e.g., $3 \times 3$ vs. $5 \times 5$) or pooling operations for each layer. The Inception Module eliminates this constraint by executing multiple pathways in parallel and concatenating their output feature maps into a single output volume.
Key Pathways in an Inception Module:
- $1 \times 1$ Convolutions: Capture fine-grained, cross-channel information without altering spatial dimensions.
- $3 \times 3$ Convolutions: Extract medium-scale spatial features (e.g., textures, mid-level patterns).
- $5 \times 5$ Convolutions: Capture larger, global spatial context (often factorized into two stacked $3 \times 3$ convolutions in later iterations like Inception-v2/v3).
- $3 \times 3$ Max-Pooling: Retains salient spatial features while preserving local structural invariance.
By combining these branches, the network seamlessly processes both localized details and broad contextual features in a single pass.
2. Computational Efficiency via $1 \times 1$ Bottlenecks
Processing large feature maps directly through $3 \times 3$ or $5 \times 5$ filters across many channels is computationally expensive. To prevent a massive explosion in parameters, the Inception architecture introduces dimensionality reduction bottlenecks.
How $1 \times 1$ Convolutions Reduce Bottlenecks:
- Channel Reduction: Before applying compute-heavy $3 \times 3$ or $5 \times 5$ convolutions, $1 \times 1$ convolutions project the input feature maps into a lower-dimensional channel space.
- Post-Pooling Compression: A $1 \times 1$ convolution is applied immediately following the max-pooling path to prevent channel overflow upon concatenation.
- Preserved Representation: This dimensional compression dramatically reduces floating-point operations (FLOPs) without discarding critical spatial information.
Key Takeaways
| Feature | Naïve Architecture | Inception Module |
| Filter Selection | Fixed filter size per layer | Parallel $1 \times 1$, $3 \times 3$, $5 \times 5$, & Pooling |
| Feature Extraction | Single spatial resolution | Multi-scale spatial resolutions simultaneously |
| Computational Cost | High FLOP count for large kernels | Reduced via $1 \times 1$ bottleneck convolutions |
| Network Capability | Deeper stacks risk overfitting | Wider, multi-path layers increase capacity efficiently |
By decoupling layer depth from computational cost, the Inception Module enables deeper, wider neural networks that maintain high accuracy and computational efficiency on complex visual tasks.
Architecture of Inception Networks (GoogLeNet)
Introduced by Szegedy et al. in 2014, the original Inception Network (GoogLeNet) revolutionized deep learning for computer vision. By stacking custom Inception Modules into a unified, deep neural network, GoogLeNet achieved state-of-the-art performance across image classification, object detection, and semantic segmentation while remaining computationally efficient.
Read more blog : VGG Architecture Explained: How It Revolutionized Deep Neural Networks
1. Hierarchical Stacking of Inception Blocks
Rather than relying purely on standard sequential convolutions, the Inception Network connects multiple Inception modules hierarchically into cohesive blocks.
- Low-Level Feature Extraction: Early layers focus on spatial primitives such as edges, color gradients, and fine textures.
- Mid-to-High-Level Abstraction: Deeper Inception blocks combine multi-scale receptive fields to learn complex object parts and full semantic concepts.
- Controlled Depth: Stacking these modular blocks allows the network to grow 22 layers deep without suffering from prohibitive computational overhead.
2. Key Architectural Innovations
Beyond multi-path feature extraction, GoogLeNet introduced two critical structural mechanisms to optimize training stability and parameter efficiency:
A. Auxiliary Classifiers for Gradient Flow
Deep networks often suffer from the vanishing gradient problem, where error signals dissipate before reaching early layers. To combat this:
- Intermediate Branches: Auxiliary classification heads are inserted at intermediate stages of the network during training.
- Gradient Injection: These side-branches compute additional training loss, pushing strong, non-dissipating gradient signals directly into lower layers.
- Inference Efficiency: The auxiliary heads are discarded during prediction time, leaving inference speed completely unaffected.
B. Global Average Pooling (GAP)
Traditional CNNs used large, dense Fully Connected (FC) layers right before the final softmax output, which accounted for over 80% of total network parameters and caused severe overfitting risks.
- Spatial Aggregation: GoogLeNet replaces dense FC layers with a single Global Average Pooling layer that averages each feature map down to a $1 \times 1$ spatial value.
- Parameter Reduction: This shift drastically drops total trainable parameters (down to ~6.8 million, compared to VGG-16’s 138 million) while enhancing generalization across spatial translations.
Summary of Architectural Components
| Component | Architectural Function | Core Benefit |
| Inception Modules | Parallel $1\times1, 3\times3, 5\times5$ convolutions & pooling | Multi-scale feature extraction in a single layer |
| $1 \times 1$ Bottlenecks | Dimensionality compression prior to large spatial filters | Controls parameter count and FLOP requirements |
| Auxiliary Classifiers | Intermediate loss heads active during training only | Prevents vanishing gradients in deep layers |
| Global Average Pooling | Averages spatial feature maps before final classification | Replaces parameter-heavy dense layers & reduces overfitting |
Applications of Inception Networks:
The versatility and effectiveness of Inception Networks have made them indispensable across a wide range of applications in computer vision and beyond. Some notable applications include:
- Image Classification: Inception Networks excel at classifying images into predefined categories with high accuracy, making them ideal for tasks such as object recognition, scene understanding, and image retrieval.
- Object Detection: Inception Networks have been successfully applied to object detection tasks, where the goal is to localize and classify objects within an image. By leveraging their hierarchical representations, these networks can accurately detect objects of varying scales and aspect ratios.
- Semantic Segmentation: Inception Networks have shown promising results in semantic segmentation, a task that involves assigning a class label to each pixel in an image. By capturing both local and global contextual information, these networks can generate precise and detailed segmentation maps, facilitating tasks such as image editing and medical image analysis.
- Transfer Learning: Inception Networks are often used as feature extractors in transfer learning scenarios, where pre-trained models are fine-tuned on target datasets with limited annotations. By leveraging the rich hierarchical representations learned from large-scale datasets, these networks can generalize well to new tasks and domains with minimal training data.
Impact and Future Directions of Inception Networks
The introduction of the Inception Module marked a pivotal turning point in deep learning. Prior to GoogLeNet, expanding network capacity typically meant simply stacking deeper sequential layers—a strategy limited by exploding parameter counts and vanishing gradients. Inception proved that networks could grow wider and computationally richer while remaining parameter-efficient.
1. Industry & Architectural Impact
The design principles behind the Inception architecture transformed computer vision research, setting new benchmarks on the ImageNet Challenge (ILSVRC 2014) and directly inspiring subsequent generations of neural network design:
- Pioneering Multi-Scale Perception: Popularized parallel multi-kernel operations within a single layer, enabling models to capture local details and global context concurrently.
- Standardizing Channel Bottlenecks: Demonstrated that $1 \times 1$ convolutions can dramatically reduce floating-point operations (FLOPs) without sacrificing representation quality.
- Inspiring Edge AI Architectures: The emphasis on bottleneck compression directly influenced lightweight mobile vision backbones, including MobileNets, ShuffleNets, and SqueezeNet.
- Iterative Evolution: Catalyzed a series of influential models, including Inception-v2/v3 (introducing factorized convolutions), Inception-v4, and Inception-ResNet (integrating residual connections with multi-path blocks).
2. Legacy in Modern Deep Learning
As artificial intelligence shifts toward resource-constrained deployment and hybrid multi-modal architectures, the core principles of Inception remain highly relevant:
A. Efficient Structural Design
Inception shifted deep learning research from brute-force depth stacking toward structural efficiency. This mindset laid the theoretical groundwork for modern Neural Architecture Search (NAS) and automated hardware-aware model design.
B. Cross-Pollination with Vision Transformers (ViTs)
Modern hybrid architectures (such as CoAtNet and ConvNeXt) frequently combine convolutional spatial inductive biases with attention mechanisms. This design echoes Inception’s core philosophy: processing fine spatial details alongside broad contextual dependencies within the same layer block.
C. Resource-Constrained Intelligence
With the rise of edge computing in robotics, mobile hardware, and IoT devices, Inception’s lesson—that high model capacity does not require high parameter density—remains a guiding principle for real-time AI.
Read more blog : Machine Learning Interview Questions for Software Engineers: A Complete Preparation Guide
Architectural Legacy Comparison
| Domain | Pre-Inception Standard | Inception-Driven Legacy |
| Network Scaling | Deep sequential layer stacking | Multi-path width and depth efficiency |
| Compute Control | Unchecked feature map volume inflation | $1 \times 1$ bottleneck compression |
| Gradient Flow | High risk of vanishing gradients in deep layers | Auxiliary loss injection & balanced multi-path gradient pathways |
| Modern Relevance | Dense monolithic backbones | Efficient feature extractors & hybrid CNN-Transformer backbones |
Conclusion:
In conclusion, the Inception Module and its eponymous network represent a significant milestone in the evolution of deep learning architectures. By embracing parallel processing, dimensionality reduction, and hierarchical representations, these models have demonstrated unparalleled performance and efficiency across a wide range of computer vision tasks. As researchers continue to build upon this foundation, the legacy of the Inception Module is poised to endure, driving innovation and progress in the field of artificial intelligence for years to come.
Frequently Ask Question:
What makes the Inception Module different from standard CNN layers?
Unlike traditional Convolutional Neural Network (CNN) layers that apply a single, fixed filter size (e.g., $3 \times 3$), an Inception Module applies multiple parallel operations—including $1 \times 1$, $3 \times 3$, and $5 \times 5$ convolutions alongside max-pooling—within the same layer. This allows the network to process spatial features at different scales simultaneously.
2. What is the role of $1 \times 1$ convolutions in the Inception architecture?
$1 \times 1$ convolutions act as dimensionality reduction bottlenecks. By compressing the number of input channels before passing feature maps to compute-heavy $3 \times 3$ or $5 \times 5$ filters, they dramatically reduce the total floating-point operations (FLOPs) and computational cost without sacrificing valuable information.
3. Why were auxiliary classifiers added during training?
Auxiliary classifiers were extra intermediate loss heads added to middle layers of the deep network to inject fresh gradient signals during backpropagation. This mitigated the vanishing gradient problem in early layers. These side heads were used during training only and discarded at prediction time.
4. How does Global Average Pooling (GAP) prevent overfitting?
Inception replaced parameter-heavy Fully Connected (FC) layers at the end of the network with a single Global Average Pooling layer. GAP reduces each feature map to a single scalar value, cutting total network parameters drastically (from over 100 million in models like VGG down to ~6.8 million in GoogLeNet) and reducing overfitting risks.
5. Are Inception Networks still relevant in modern deep learning?
Yes. While pure Inception models have evolved into newer versions (Inception-v3, Inception-ResNet), their core concepts—such as multi-scale feature extraction, bottleneck compression, and parallel processing—heavily influence modern MobileNets, edge AI architectures, and hybrid CNN-Transformer backbones used today.
