

Modern applications cannot scale without a resilient, well-engineered database layer. When system traffic surges, the database design is almost always the first bottleneck to trigger latency spikes, connection exhaustion, and cascading service failures.
Building a database architecture that scales from day one requires a systematic approach to data modeling, storage engines, indexing strategies, caching patterns, and ongoing performance tuning.
1. Requirement Profiling & Workload Analysis
Before writing a schema or selecting an engine, define the exact workload characteristics the database will process. Designing without these parameters leads to premature optimization or catastrophic under-provisioning.
- Read vs. Write Distribution: A read-heavy application (e.g., 90:10 read-to-write on social media feeds) benefits from aggressive caching, read replicas, and denormalized views. A write-heavy system (e.g., 20:80 on IoT telemetry or financial ledgers) requires sequential append-only writes, LSM-tree-based engines, and write-ahead buffers.
- Access Patterns & Key Paths: Map out high-frequency queries, filtering criteria, and sorting requirements. Identify which operations require strict consistency versus those that tolerate eventual consistency.
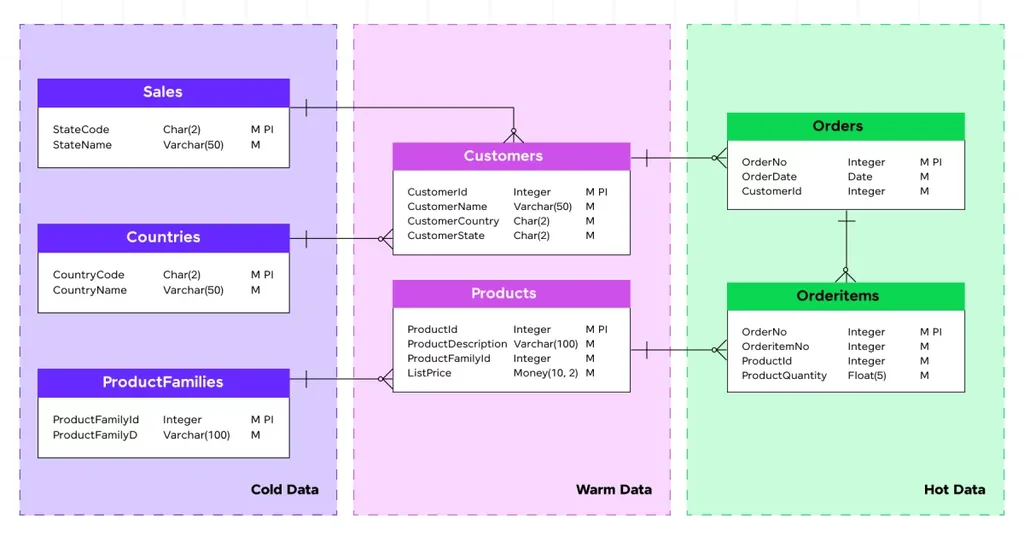
- Data Lifecycle & Growth Trajectory: Estimate initial storage, daily ingest rates, peak throughput (QPS/TPS), and retention requirements. Plan for hot storage (low latency), warm storage (frequent access), and cold storage (long-term archive).
- SLA & Latency Budgets: Set concrete performance targets, such as maintaining p95 latency under 50ms and p99 latency under 150ms under peak concurrent loads.
2. Storage Engine & Database Selection
No single database fits every workload. High-scale architectures often adopt Polyglot Persistence, using different database technologies for distinct domain boundaries.
                               ┌── Relational (PostgreSQL/MySQL) ── Transactional Data (ACID)
                               │
Application Service Layer ─────┼── Key-Value (Redis/DynamoDB) ───── Sessions, Caching, Rate Limits
                               │
                               ├── Document / Wide-Column ───────── Catalogs, Event Streams
                               │   (MongoDB / Cassandra)
                               │
                               └── Search Engine (Elasticsearch) ── Full-Text & Analytics
| Engine Type | Ideal Use Case | Strengths | Trade-Offs | Industry Examples |
| Relational (RDBMS) | Financial systems, ERPs, core user accounts | ACID compliance, complex relational joins, data integrity | Horizontal scaling complexity, rigid schemas | PostgreSQL, MySQL |
| Document Store | Content management, user profiles, e-commerce catalogs | Flexible schemas, nested hierarchical data models | Potential duplication, weak cross-document integrity | MongoDB, Couchbase |
| Key-Value Store | Session management, caching, real-time leaderboards | Single-digit millisecond latency, high concurrency | Minimal querying capabilities beyond the primary key | Redis, DynamoDB |
| Wide-Column | Time-series metrics, IoT sensor data, event logs | Linear write scalability, robust multi-region distribution | Complex query planning, absence of ad-hoc joins | Apache Cassandra, ScyllaDB |
| Graph Database | Fraud detection, social networks, knowledge graphs | Rapid traversal of interconnected entity relationships | Steep learning curve, difficult to partition across clusters | Neo4j, Amazon Neptune |
3. Normalization vs. Strategic Denormalization
Data modeling is an ongoing balance between transactional consistency and read performance.
- Third Normal Form (3NF): Ensures every non-key column depends strictly on the primary key, eliminating data duplication and write anomalies. Essential for transactional accounting and payment processing.
- Denormalization for Throughput: Complex SQL
JOINoperations across massive tables degrade performance at high concurrency. Selectively duplicating fields (e.g., embedding customer names directly within an order record) eliminates joins and lowers query latency. - Materialized Views: Precompute complex aggregations asynchronously on a schedule or via change-data-capture (CDC) triggers, ensuring analytical reads never block transactional writes.
4. Indexing Strategies & Engine Internals
Indexes turn full-table scans into targeted lookups, but each additional index incurs write overhead, memory consumption, and disk I/O.
- B-Tree Indexes: The default for standard equality and range queries (
=,<,>,BETWEEN). They maintain a balanced search tree for logarithmic lookup times. - Covering Indexes: Include all columns requested by a query within the index itself (e.g., using
INCLUDEclauses). This allows the database to return results directly from the index tree without fetching the underlying table page (an Index-Only Scan). - Composite Indexes & The Leftmost Prefix Rule: When querying across multiple columns, build compound indexes ordered by cardinality:$$\text{Index Order: } (A, B, C) \implies \text{Valid for queries on } (A), (A,B), (A,B,C)$$
- Partial (Filtered) Indexes: Index only a subset of rows using a predicate (e.g.,
WHERE status = 'pending'). This keeps the index footprint small and fast while ignoring inactive historical data. - Write Penalty Mitigation: Audit and prune unused indexes regularly using database statistics views like PostgreSQL’s
pg_stat_user_indexes.
5. Horizontal & Vertical Partitioning Strategies
When datasets outgrow single-server memory and compute bounds, partitioning isolates workloads and maintains query performance.
- Horizontal Sharding: Distributes rows across distinct physical database instances using a Shard Key.
- Hash-Based Sharding: Applies a hash function to the key for uniform distribution across nodes, avoiding hotspots.
- Range-Based Sharding: Splits data by discrete intervals (e.g., order dates), ideal for time-series queries but prone to write hotspots on the latest range.
- Vertical Partitioning: Splits table columns into dedicated tables. High-frequency, lightweight columns remain in the core table, while large, infrequently accessed fields (e.g.,
BLOB,TEXT, profile descriptions) are stored separately. - Partition Pruning: Enables the query optimizer to scan only relevant physical partitions rather than the entire table space during query execution.
6. Multi-Tiered Caching & Invalidation Patterns
Shield the persistent storage tier by serving reads from fast, volatile in-memory layers.
Client Request ──► Application Layer ──► Cache Tier (Redis) ──► Hit: Return Immediate
                                             │
                                         Miss: Read DB ──► Populate Cache ──► Return
- Cache-Aside (Lazy Loading): The application checks the cache first. On a cache miss, it reads from the database, writes the result to the cache, and returns the response.
- Write-Through / Write-Behind: Data is written to the cache first. In write-through, it writes synchronously to the database; in write-behind, it batches writes asynchronously for higher write throughput.
- Mitigating Common Failure Modes:
- Cache Stampede (Thundering Herd): Use mutex locks or probabilistic early expiration to prevent thousands of concurrent requests from hitting the database simultaneously when a hot key expires.
- Cache Penetration: Store empty/null results with short TTLs or implement Bloom filters at the boundary to block queries for non-existent records.
7. Performance Monitoring & Query Optimization
Continuous database optimization relies on metrics and execution plans rather than guesswork.
- Execution Plan Analysis: Run
EXPLAIN (ANALYZE, BUFFERS)to spot costly operations such as sequential table scans, nested loop joins on large sets, and disk-spilled sorting steps. - Connection Pooling: Direct database connections consume significant RAM and process overhead. Deploy lightweight connection poolers (e.g., PgBouncer, HikariCP) to multiplex client connections efficiently.
- Routine Engine Hygiene: Schedule non-blocking table vacuuming, statistics updates (
ANALYZE), and index defragmentation (REINDEX CONCURRENTLY) during off-peak windows. - Database Telemetry: Track key operational metrics, including slow query counts, replication lag, disk I/O utilization (IOPS limits), lock wait durations, and connection pool saturation.
Read more blog: 5 Key Components of a Scalable Backend System
8. Elasticity & High Availability Planning
A scalable database design must withstand infrastructure failures while dynamically adapting to traffic demands.
- Read Replication & Load Balancing: Deploy read replicas behind a database load balancer (e.g., HAProxy, ProxySQL) to handle heavy analytical and read traffic, reserving the primary node strictly for write operations.
- Automated Failover Mechanisms: Implement consensus-driven clustering (e.g., Patroni for PostgreSQL, Raft-based orchestrators) to promote standby replicas to primary status within seconds during hardware faults.
- Chaos & Load Testing: Validate performance limits prior to production releases using realistic load-testing tools (e.g.,
sysbench,pgbench, Locust) to verify failover automation and discover query bottlenecks under stress.
Conclusion
Scalable database architecture requires finding the right balance between relational integrity, access speed, and operational complexity. By understanding workload requirements early, choosing the right storage model, indexing intentionally, and isolating read traffic with multi-tiered caching, engineering teams can build resilient systems that support sustained long-term growth.
Read more blog : What does SaaS architecture look like behind modern cloud applications?
Frequently Ask Question:
1. How do I decide whether to normalize or denormalize my database?
Answer: Start with a normalized structure (up to 3NF) to ensure data integrity and prevent write anomalies. Transition to strategic denormalization (such as embedding related fields or precalculating aggregates) only when read-heavy workloads or expensive multi-table joins create measurable performance bottlenecks at scale.
2. When should an application switch from a single relational database to sharding?
Answer: Sharding introduces significant operational and querying complexity. Before sharding horizontally across multiple physical nodes, exhaust vertical scaling, query optimization, indexing improvements, read replication, and caching layers. Consider sharding when write throughput exhausts the single primary node’s I/O or the dataset outgrows single-instance storage and memory limits.
3. What is the difference between Cache-Aside and Write-Through caching?
Answer: While indexes accelerate SELECT operations, every insert, update, or delete requires the database to update the corresponding index structures (such as B-Trees) on disk and in memory. Excessive indexing increases write latency, consumes additional disk storage, and occupies valuable RAM in the database buffer pool.
5. How does replication lag impact read replicas in high-scale systems?
Answer: In asynchronous replication setups, there is a slight delay between a write hitting the primary database and being reflected on read replicas. This can cause stale reads (e.g., a user updates their profile but immediately sees old data after refreshing). Applications handle this by routing critical, time-sensitive reads to the primary database or using session-level read-your-own-writes consistency models.
